Authors
Everything in this page is done from AdminCentral. You never edit a file.
The pack gives you five things, and they live in two places — the form you already use to edit content, and one app of its own:
| What you want to do | Where you do it |
|---|---|
| Decide how a page or an item looks on Google, on social networks and to an AI assistant | The [H1] SEO tab, inside the page properties or the item form |
Keep sitemap.xml current |
Nothing to do — it is generated. You only tune it per page, in the same tab |
| Change the rules crawlers must follow | The robots.txt content field of the robots page |
Publish the site index AI assistants read (llms.txt) |
Nothing to do — it is generated from what you already wrote |
| Send an old address to a new one | The [H1] SEO › Redirects app |
Your first pass on a page
If you only have ten minutes for a page, do these five things in this order. Everything else has a sensible default.
| # | Where | What to do |
|---|---|---|
| 1 | [H1] SEO › Metadata › Content | Write the Title (50–60 characters, keyword first, brand last). |
| 2 | Same panel | Write the Description (140–160 characters, value proposition and a call to action). |
| 3 | Same panel | Write the Summary / TL;DR in one to three plain sentences. It is the one field that feeds AI search and llms.txt. |
| 4 | Metadata › Social | Pick a Social image, 1200×630, subject centred. |
| 5 | Metadata › Structured data / GEO | Set the Schema.org type if the page is not a plain WebPage, and add three to six Topics / entities. |
Save, and you are done: the canonical address, the social card, the crawler instruction, the dates, the structured data and the publisher block are generated for you.
The [H1] SEO tab
Page properties have a tab called [H1] SEO, and the content apps that have been enabled for it have the same tab in the item form. The fields are identical in both places: a catalog product is optimised where you edit the product, not somewhere else.
Inside the tab you will find one or two panels — Metadata and Sitemap — depending on where you are. If you expect a panel and it is not there, that is a one-time setup job for a developer, described in Developers · Installation.
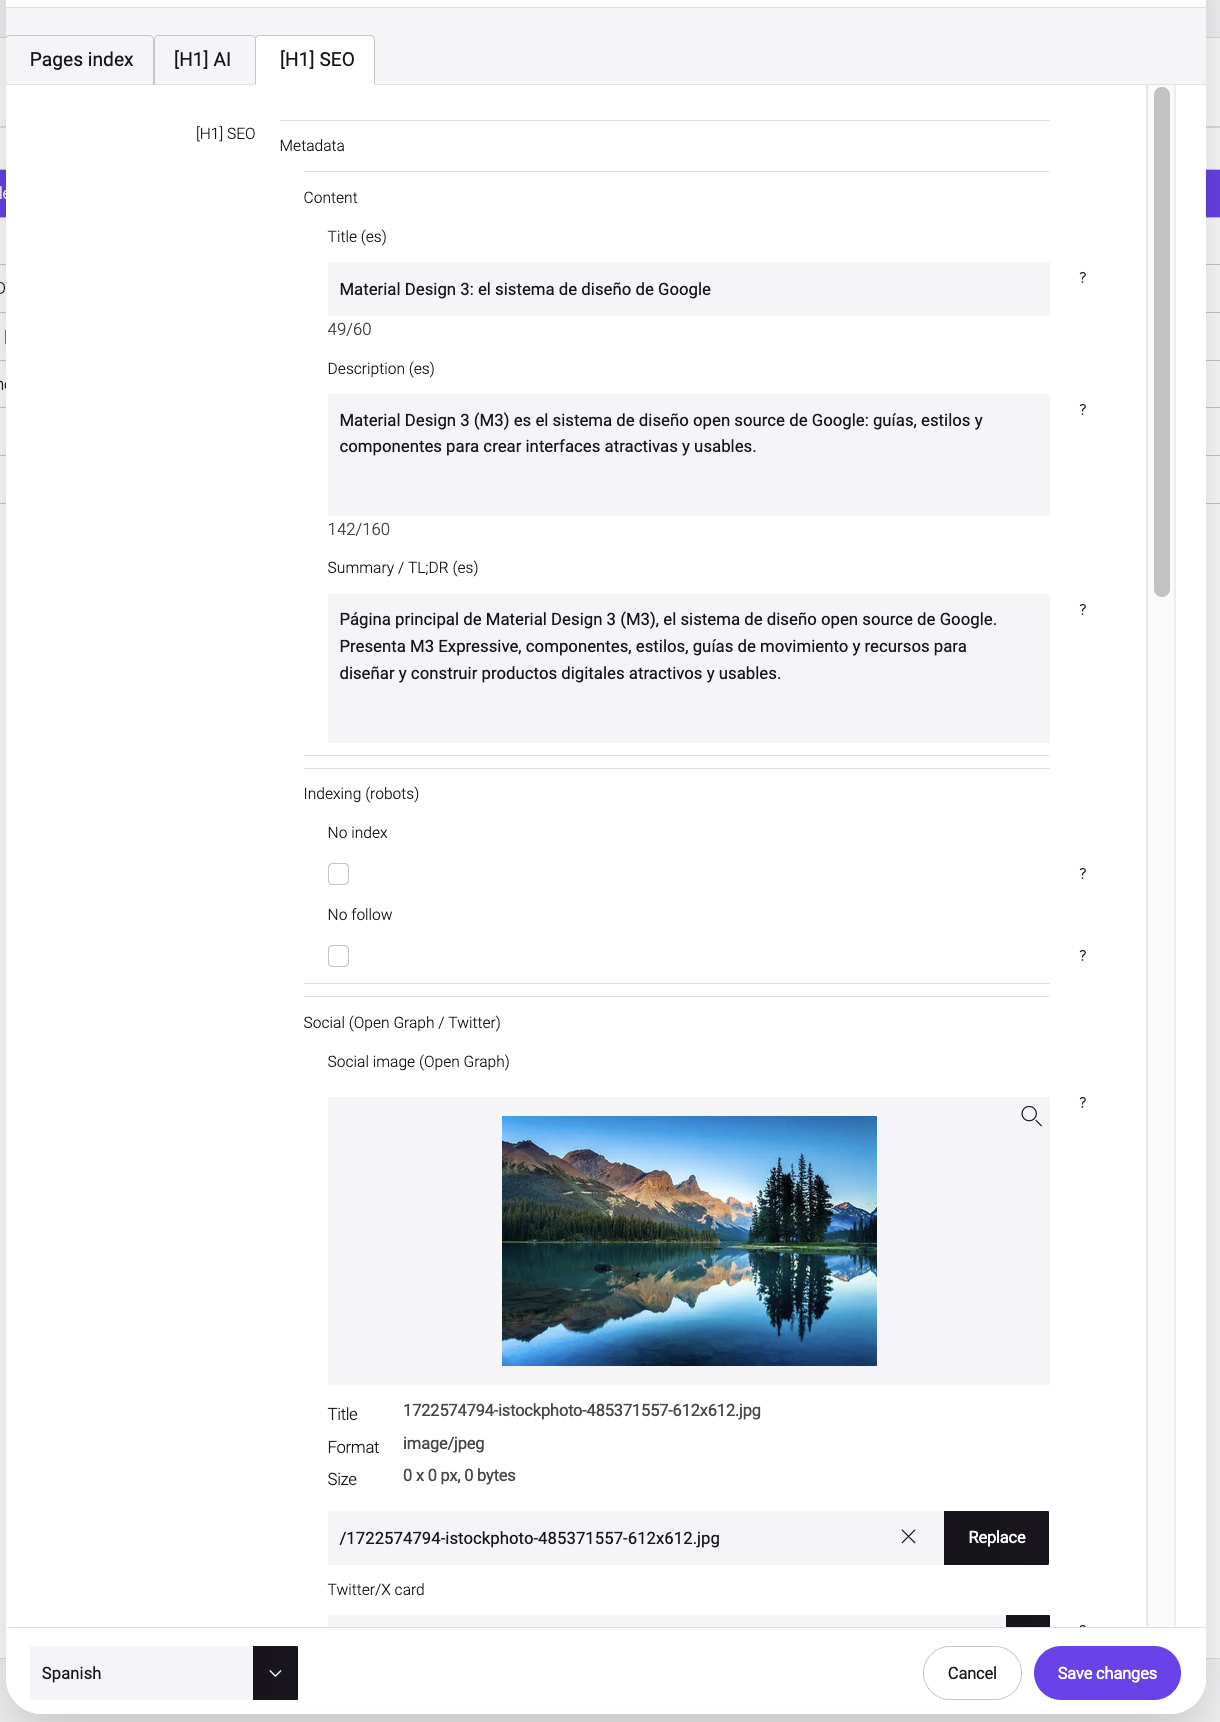
Where the tab appears
| Where | Panels you get | Why |
|---|---|---|
| Most page templates | Metadata + Sitemap | A normal page has its own address and its own metadata. |
| A detail template that renders a collection (a case study detail, for example) | Sitemap only | The template's own address is never published — the sitemap publishes one address per item instead. |
| Products and Case studies item forms | Metadata only | The item is not a page, so there is nothing per-page to tune in the sitemap. |
Content
| Field | What it does |
|---|---|
| Title | The blue link Google shows in its results, and the title of the social card. Put the main keyword first and the brand last ("Running shoes | Brand"). Recommended 50–60 characters, max. 60 — the field stops you at 60. Per language. |
| Description | The grey snippet under the title, and the description of the social card. One or two sentences with the value proposition and a call to action. Recommended 140–160 characters, max. 160 — the field stops you at 160. Per language. |
| Summary / TL;DR | A short factual summary in plain language, one to three sentences — what you would tell a person, or an AI, about this page. It feeds AI search and it is the description used in llms.txt. No length limit. Per language. |
Empty fields fall back, they never break anything. An empty Title uses the item's own title
(for catalog items, its name). An empty Description uses the Summary / TL;DR. An empty
Summary / TL;DR simply means the link in llms.txt falls back to the description, and then to
the title. Filling these in is an improvement, never a prerequisite.
Note — these three fields are per language. Switching the language selector at the top of the dialog gives you an empty set of fields for the new language, and an untranslated language falls back to the default one. Translate the Title and the Description first; the Summary / TL;DR is the one worth translating next, because it is what an AI assistant quotes.
Indexing (robots)
| Field | What it does |
|---|---|
| No index | Asks search engines not to show this page in their results — and removes it from llms.txt. Unchecked by default. Use it on thank-you pages, internal search results and duplicates; never on a page that should rank. |
| No follow | Asks crawlers not to follow the links on this page. Unchecked by default. Rarely needed. |
Note — No index does not remove the page from the sitemap; the field for that is Exclude from sitemap, in the Sitemap panel. The two are separate on purpose: a page can be excluded from the sitemap and still be indexable through a normal link.
The three switches that hide content do not have the same reach, and mixing them up is the most common mistake on this tab:
| Switch | Hides the page from | Hides the pages underneath it? |
|---|---|---|
| No index | Search results and llms.txt |
No — the pages underneath stay visible |
| No follow | Nothing. It only asks crawlers not to follow this page's links | No |
| Exclude from sitemap | sitemap.xml |
Yes — the whole branch goes with it |
Social (Open Graph / Twitter)
| Field | What it does |
|---|---|
| Social image (Open Graph) | The image used when the page is shared. Picked from the media library. Recommended 1200×630 px, under 1 MB, with the subject centred. |
| Twitter/X card | summary_large_image (default) — a big image; or summary — a small thumbnail. |
Leave Social image empty and the site's default social image is used, when one is configured. If neither exists, the share simply has no image.
Note — the title, the description and the alternative text of the social card are not fields. They are taken from Title and Description, so a card is never out of step with the page.
Structured data / GEO
| Field | What it does |
|---|---|
| Schema.org type | What the page is, which is what enables rich results and helps AI place the content: WebPage (default), Article, Product, Organization or Person. It also decides the social type: Article shares as an article, Product as a product, everything else as a website. |
| Topics / entities | The main topics of the page, one per line. Three to six concepts in plain language (running, cushioning, neutral pronation). They help an AI understand and disambiguate the subject. |
| FAQ (Q&A) | Question and answer pairs. Google can show them as an expandable block directly in the results, and AI assistants quote them. Use real user questions with answers of one to three sentences. Per language — keep the same number of entries in the same order in every language. |
Leave them empty and the structured data is still generated, just with less detail.
Warning — the FAQ entries are a list, and the translations are attached to each entry by its position in that list. Reordering or deleting an entry in one language reorders it in every language. Add and remove entries in the default language, then translate; do not reorder a list that is already translated.
Advanced
| Field | What it does |
|---|---|
| Raw JSON-LD (override) | Structured data written by hand, for cases the fields above cannot express. It replaces the generated block entirely. Leave it empty unless you know you need it. |
Warning — Raw JSON-LD (override) must be valid JSON. When you fill it in, Schema.org type and Topics / entities stop having any effect on the structured data — your text is published instead of the generated one. The FAQ block is published separately and is not affected.
What happens on its own
You fill in what adds meaning; the plumbing is generated:
- The canonical address of the page.
- The complete social card:
og:title,og:description,og:url,og:type, the site name, the image and its alternative text (which reuses the title), and the matching Twitter/X tags. - The crawler instruction built from No index and No follow.
- The publication and update dates, taken from the page itself.
- The structured data, from Schema.org type, Topics / entities and the title and description — plus a separate FAQ block whenever you have entered questions.
- The publisher block (organisation name, type, logo and social profiles), taken from the site configuration.
SEO on catalog items, case studies and blog posts
A product, a case study and a blog post are not pages, but they are published at an address of their own, so they get the same [H1] SEO tab in their form. Three apps have it today: Products, Case studies and Blog posts.
📸 [Screenshot: the Products app detail form open on the [H1] SEO tab, showing the Metadata panel with Title and Description filled in — to make the point that it is the same tab as on a page, in the item form]
What is the same as on a page: every field, every fallback, every per-language rule.
What is different:
- There is no Sitemap panel. You do not need one. The item's address is published by the sitemap automatically, through the detail page that renders the collection — see Dynamic collections. Priority and change frequency for every item of the collection are set once, on that detail page.
- The fallbacks read the item, not a page. An empty Title falls back to the item's own name;
an empty description in
llms.txtfalls back to the item's own description, summary or subtitle. - Hiding one item is the No index checkbox on the item itself. It takes the item out of
search results and out of
llms.txt.
Sitemap
The sitemap is generated from the published pages. There is nothing to maintain and nothing to regenerate.
A developer creates one page named sitemap per site or brand — see
Developers · Installation — and from then on:
- Its location decides its scope. A
sitemappage at the root covers the whole site; asitemappage under/brand-acovers/brand-aonly. - It is served at
/sitemap.xml, and at/brand-a/sitemap.xmlfor a brand. - Its own dialog holds a single read-only field, Automatic sitemap, that restates these rules. There is nothing to fill in there.
What you do control is per page, in the Sitemap panel of the [H1] SEO tab:
| Field | What it does |
|---|---|
| Exclude from sitemap | Removes this page from the sitemap and every page under it. Unchecked by default. |
| Priority (0.0 - 1.0) | How important this page is relative to the rest, e.g. 0.8. Empty by default. |
| Change frequency (changefreq) | How often the page changes: always, hourly, daily, weekly, monthly, yearly, never. Prefilled with weekly, which is also what an empty value means. |
Left empty, Priority is calculated from how deep the page sits: 1.0 at the root, 0.1 less
per level, never below 0.1. A value outside 0.0–1.0 is refused when you save, with the message
telling you the accepted range — and so is a value that is not a number at all.
Warning — Exclude from sitemap takes the whole branch with it. Ticking it on a section landing page removes every page underneath, which is usually what you want — but it does mean one checkbox can remove many addresses at once.
There is a fourth field in that panel, Source workspace (dynamic page). It is an advanced, one-time setting a developer fills in; leave it alone. What it does is described below.
Dynamic collections
Some templates render one address per item — a case study detail, a product detail. Those pages are expanded automatically: instead of the template's own address, the sitemap gets one entry per item of the collection, built from the item's slug. Publishing a new case study adds it to the sitemap with no further action, and removing it takes it out.
The dates come from each item; the priority and the change frequency come from the template, because
all the items share it. So if you want every case study to be published with priority 0.7, you set
0.7 once — in the Sitemap panel of the detail page, not on two hundred items.
Languages
On a multilingual site each page appears once per language, and every entry carries the full set
of language alternates so Google never reads the translations as duplicates. The home page of the
default language is the one exception: it is published as /, without a language prefix, because
that is the address visitors actually land on.
On a single-language site the addresses are published plain, with no language information — which is correct: alternates for one language say nothing.
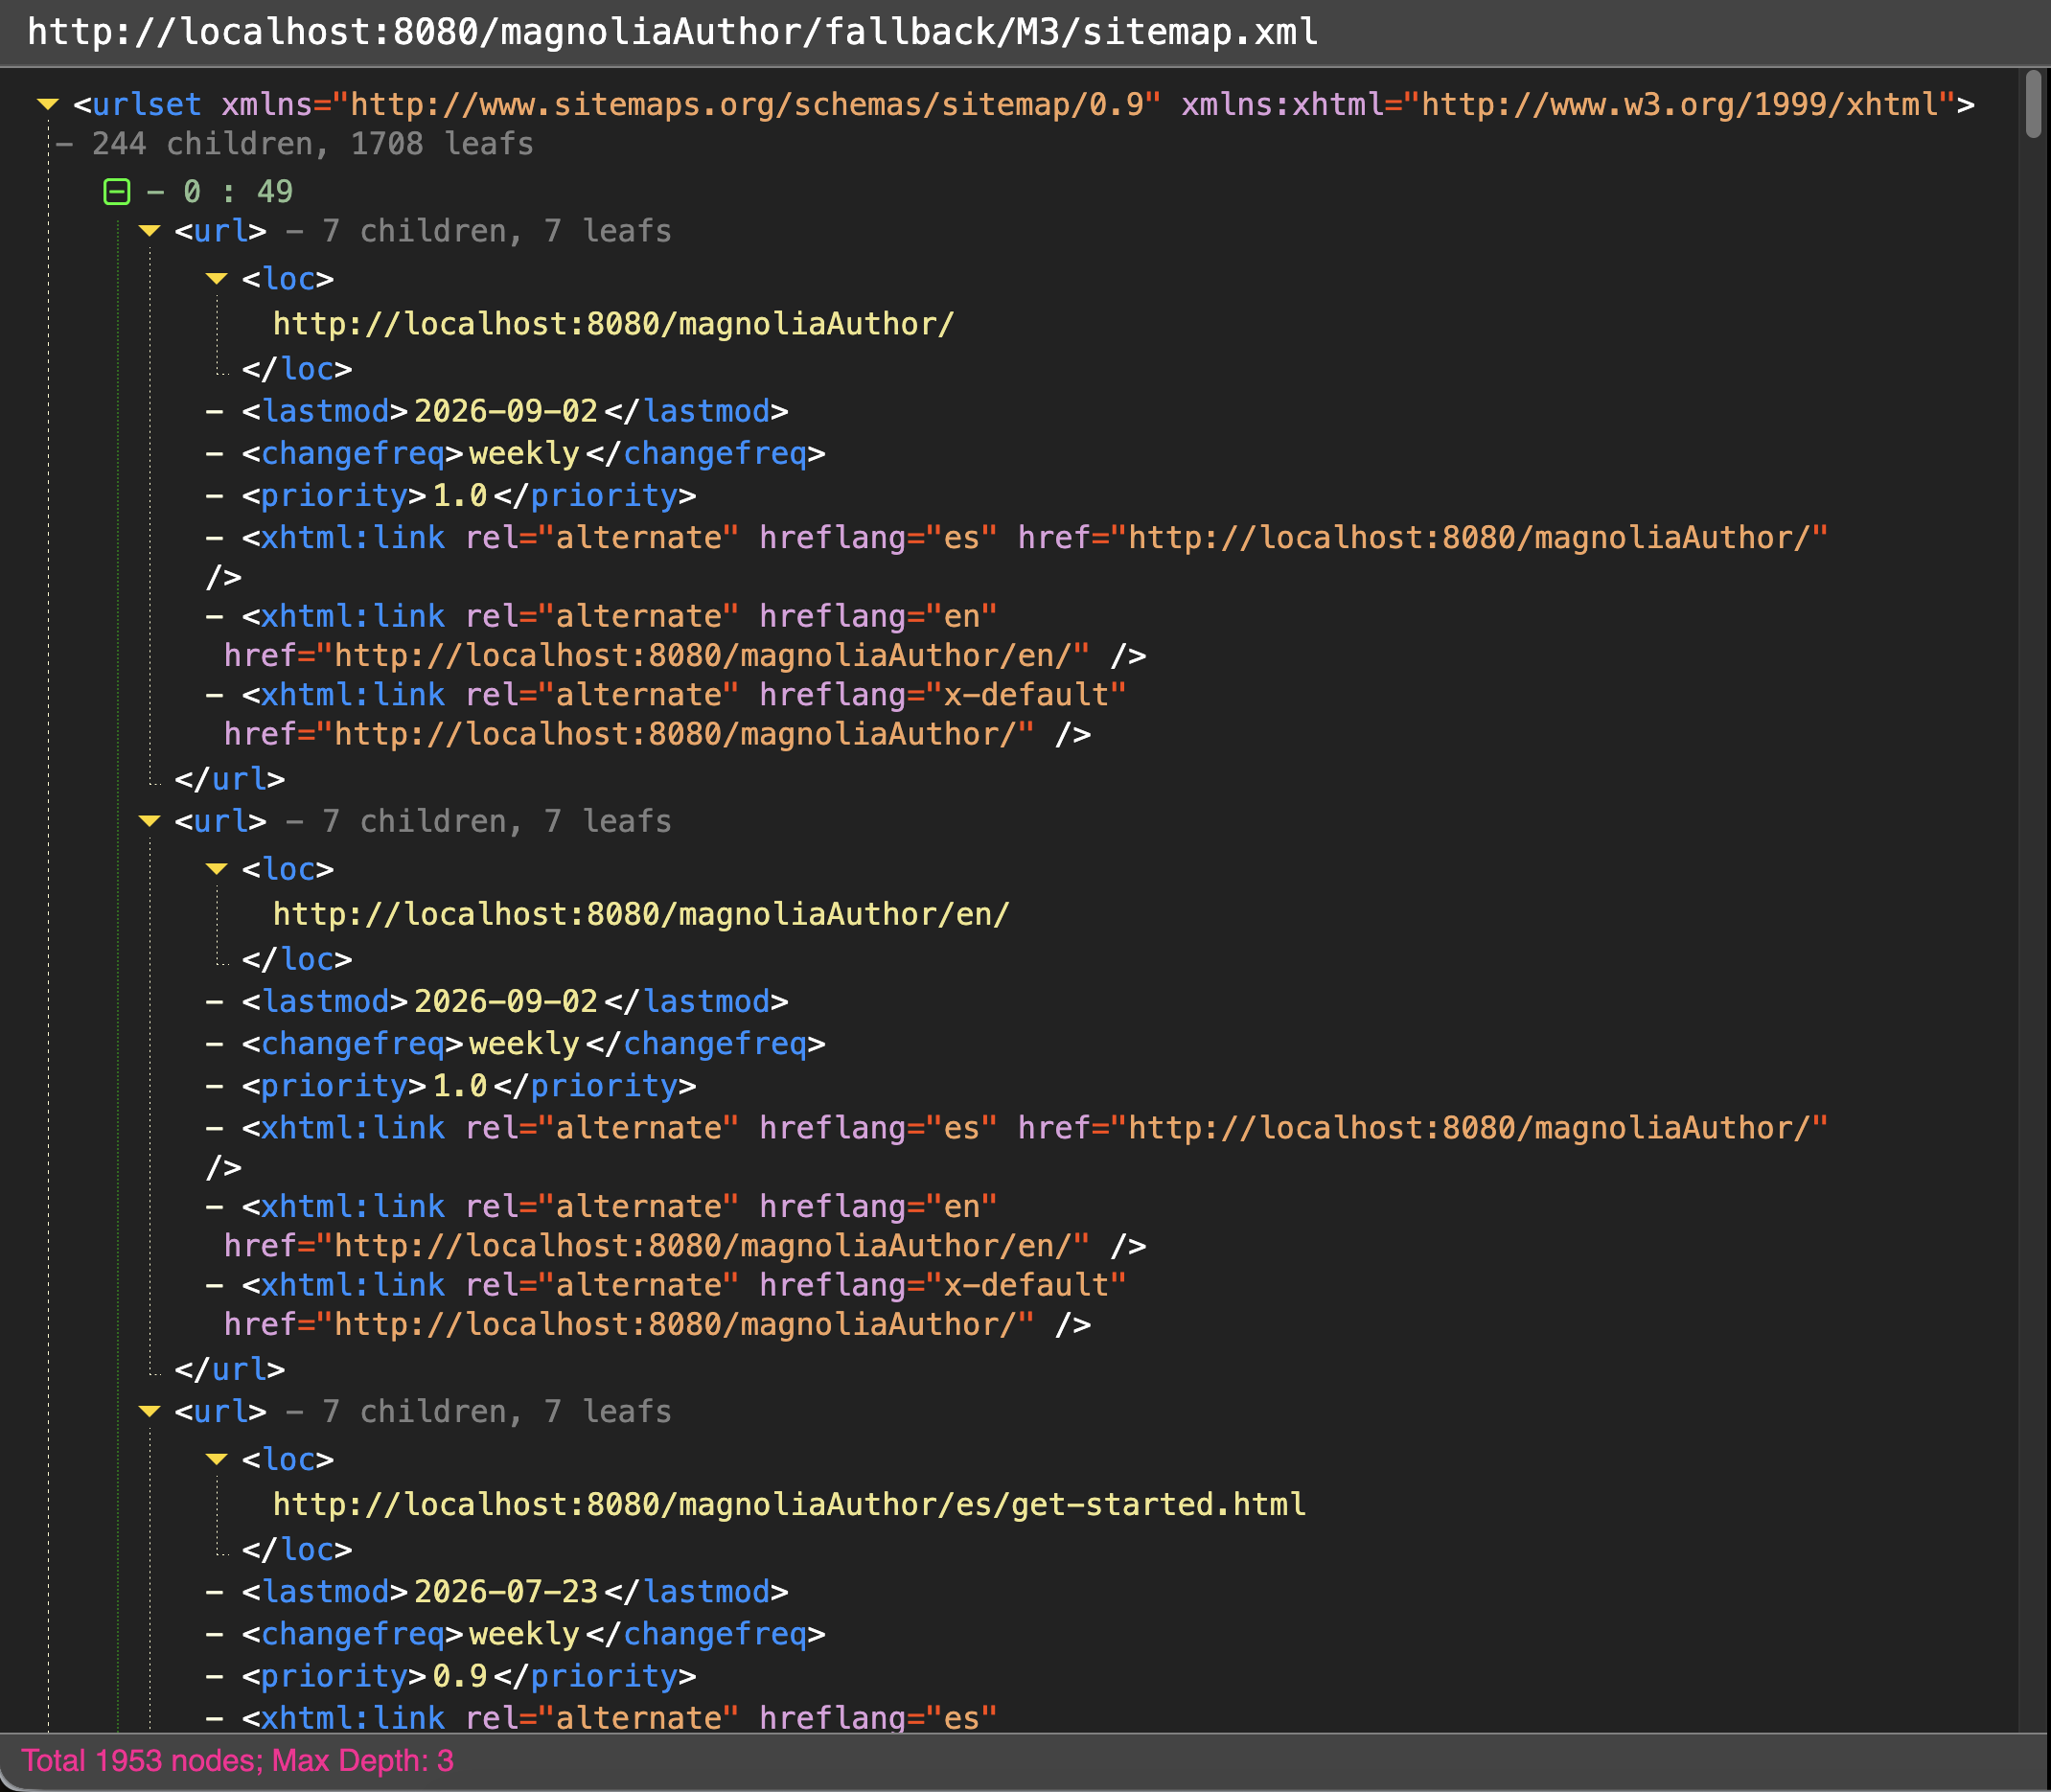
sitemap.xml. The Spanish home is published as / and the English one as /en/; x-default points at the Spanish one, and the priority drops from 1.0 at the root to 0.9 one level down.robots.txt
robots.txt is the set of traffic rules crawlers read when they arrive. It lives in a page named
robots, created once by a developer, and has one editable field.
Open the page properties and edit robots.txt content. What ships as the starting point is:
User-agent: *
User-agent: AdsBot-Google
Disallow: /admin/
Disallow: /.magnolia/
Disallow: /modules/
One directive per line. An empty field is valid and means "everything is allowed".
The directives you will actually use:
| Line | What it does |
|---|---|
User-agent: * |
Everything below applies to every crawler. Start here. |
User-agent: GPTBot |
Everything below applies to that crawler only, until the next User-agent: block. |
Disallow: /admin/ |
Asks crawlers not to request anything under that path. |
Allow: /admin/public/ |
Carves an exception out of a Disallow above it. |
Warning —
robots.txtasks crawlers not to visit a page. It does not hide it from the results: a page that is blocked here can still be listed if another site links to it. To keep a page out of search results, use No index on the page itself.Note — the
Sitemap:line is appended for you, with the right domain for whichever address the file is served from. Do not write it by hand or it will appear twice.
Same scoping rule as the sitemap: a robots page at the root serves /robots.txt, and one under
/brand-a serves /brand-a/robots.txt.
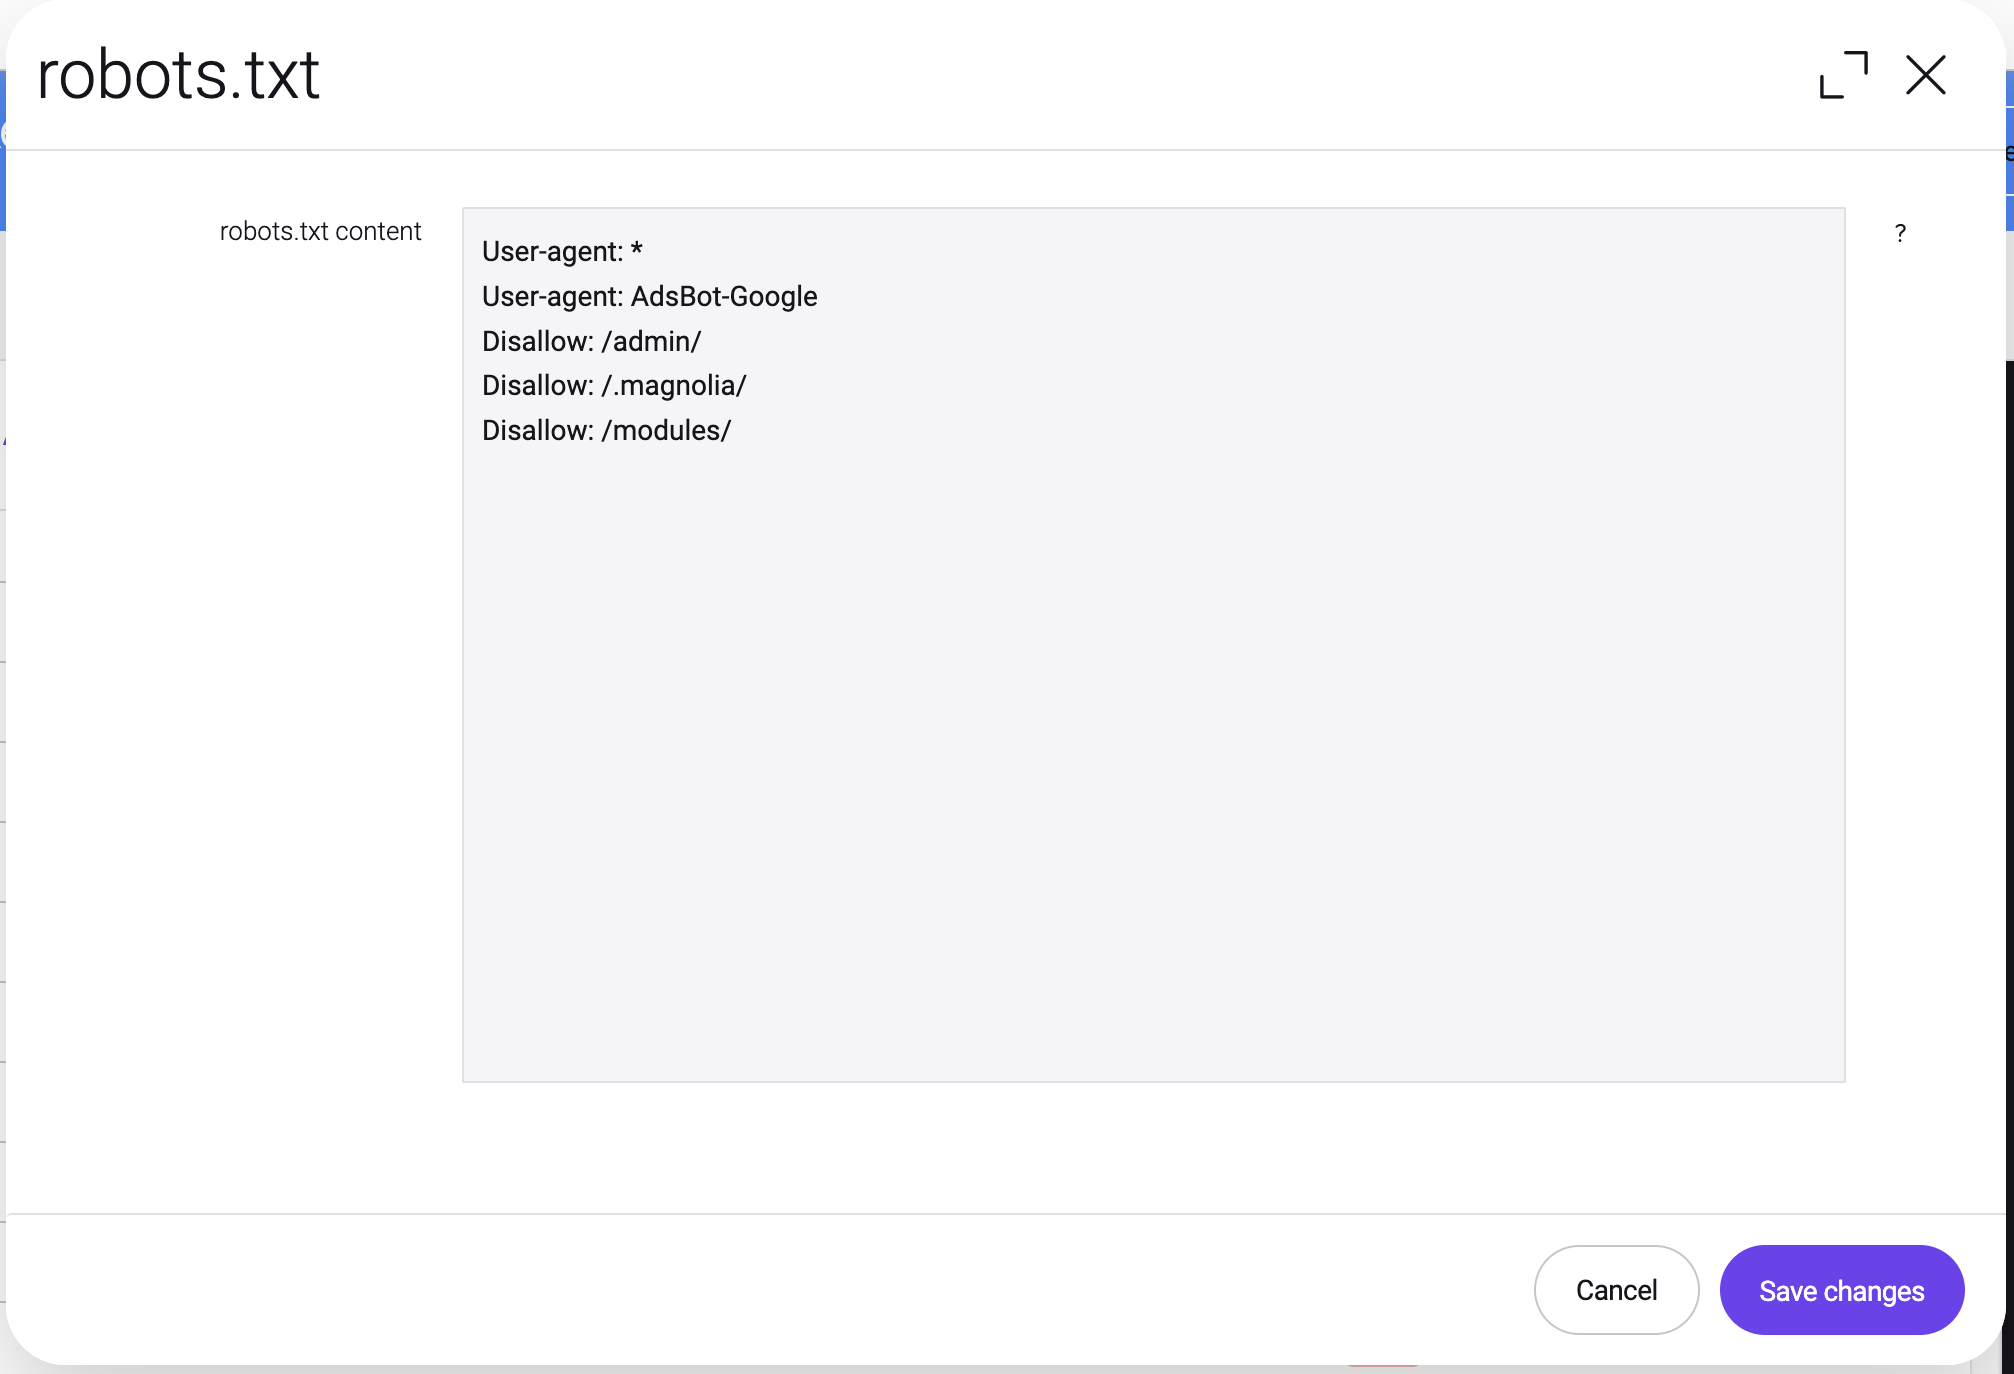
llms.txt
llms.txt is the equivalent of the sitemap, written for AI assistants — ChatGPT, Claude, Perplexity,
Gemini. It is a readable index of the site: what it is about, and which content matters.
It is fully automatic. There are no fields to fill in, because it reuses what you have already entered:
- The title and description at the top come from the site configuration.
- Each first-level page becomes a section, with its own pages nested underneath.
- Each link's description is the page's Summary / TL;DR, or its Description, or its title — whichever is filled in first. For a collection item it is the Summary / TL;DR, then the item's own description, summary or subtitle.
- Pages marked No index are left out. Your decision about search engines applies to AI too — though, unlike Exclude from sitemap, the pages underneath a hidden page still appear.
- Dynamic collections are expanded, exactly as in the sitemap.
- The
sitemap,robotsandllmspages themselves never appear.
It is served at /llms.txt, and at /brand-a/llms.txt for a brand. Its dialog holds a single
read-only field, Automatic llms.txt.
To improve what it says, fill in Summary / TL;DR on the pages that matter. That is the only lever, and it is the same field that feeds the search snippet.
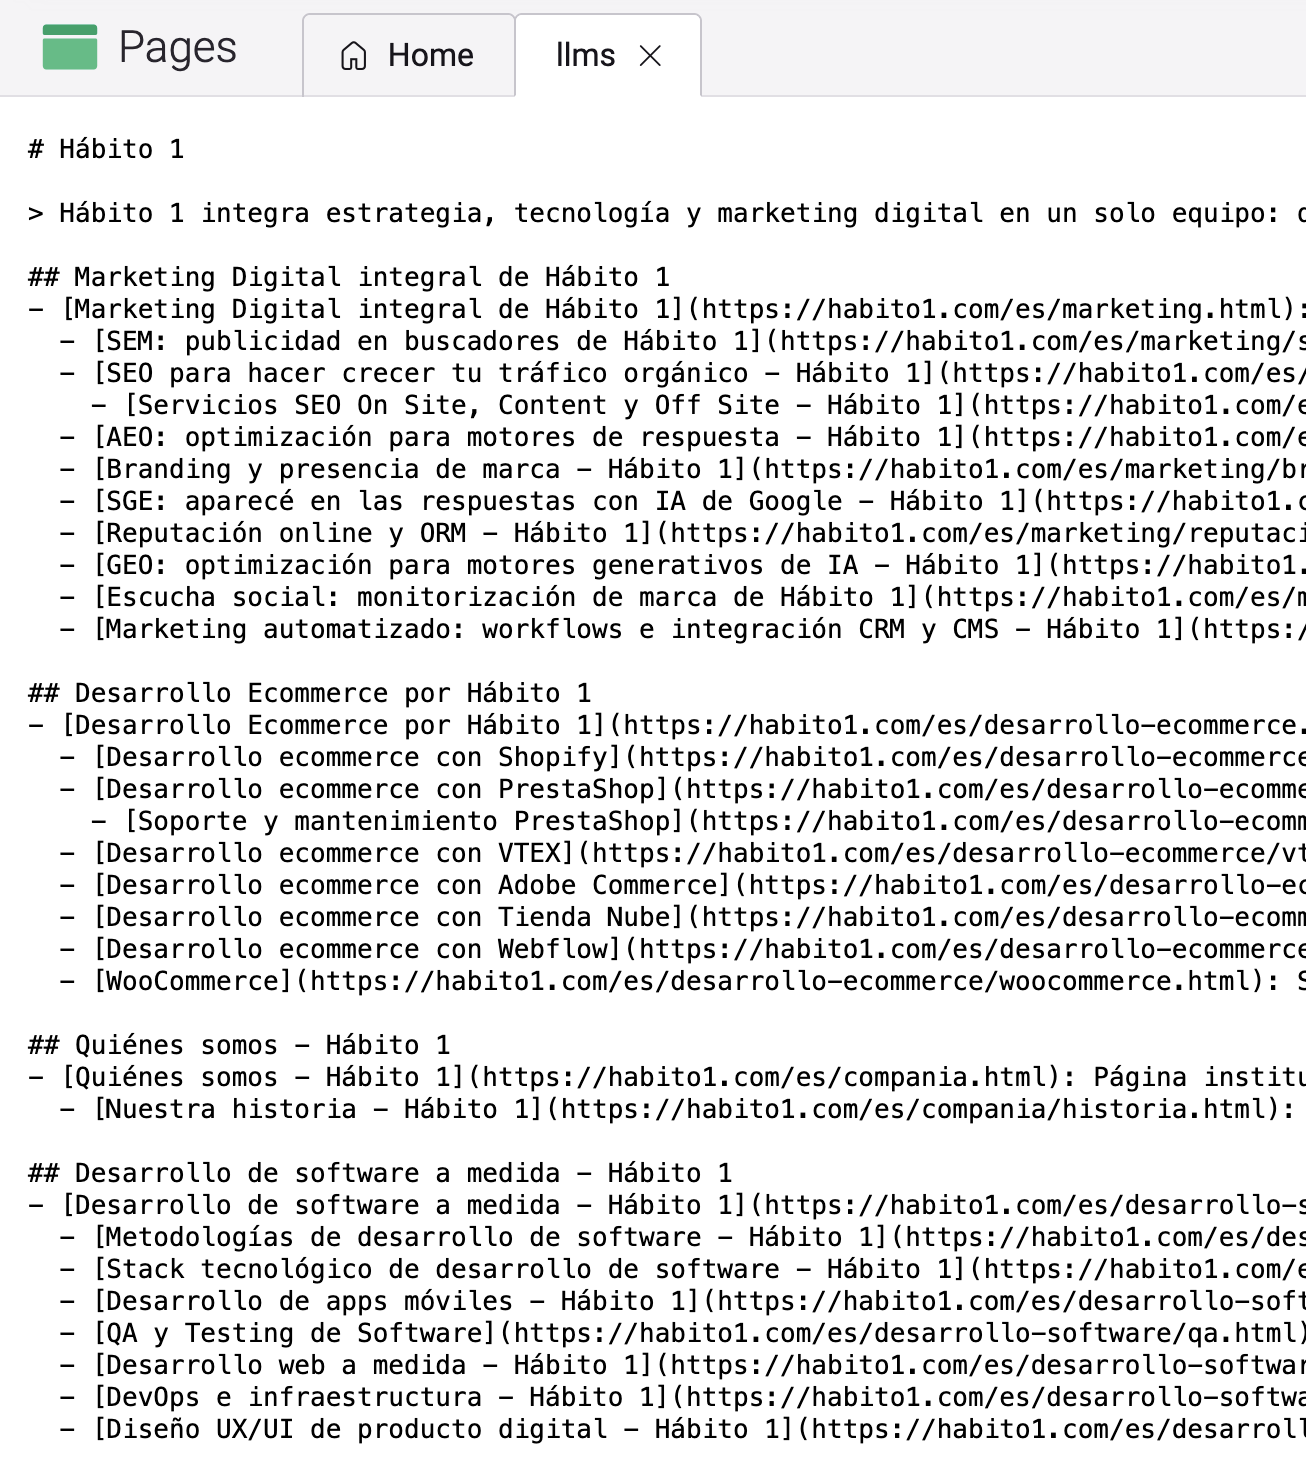
The Redirects app
Open [H1] SEO › Redirects. Each rule sends visitors from an old address to a new one, which is what protects your ranking when a site is redesigned, a section is renamed or a platform is migrated.
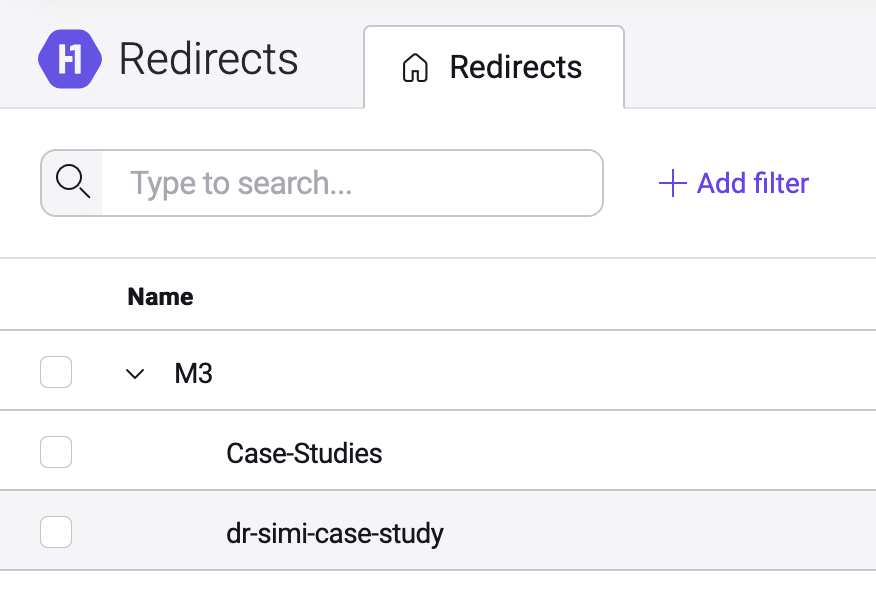
Rules are grouped in folders — one per brand, and any subfolders you find useful. The folders keep the list readable; see Where rules apply for what they do and do not change.
Creating a rule
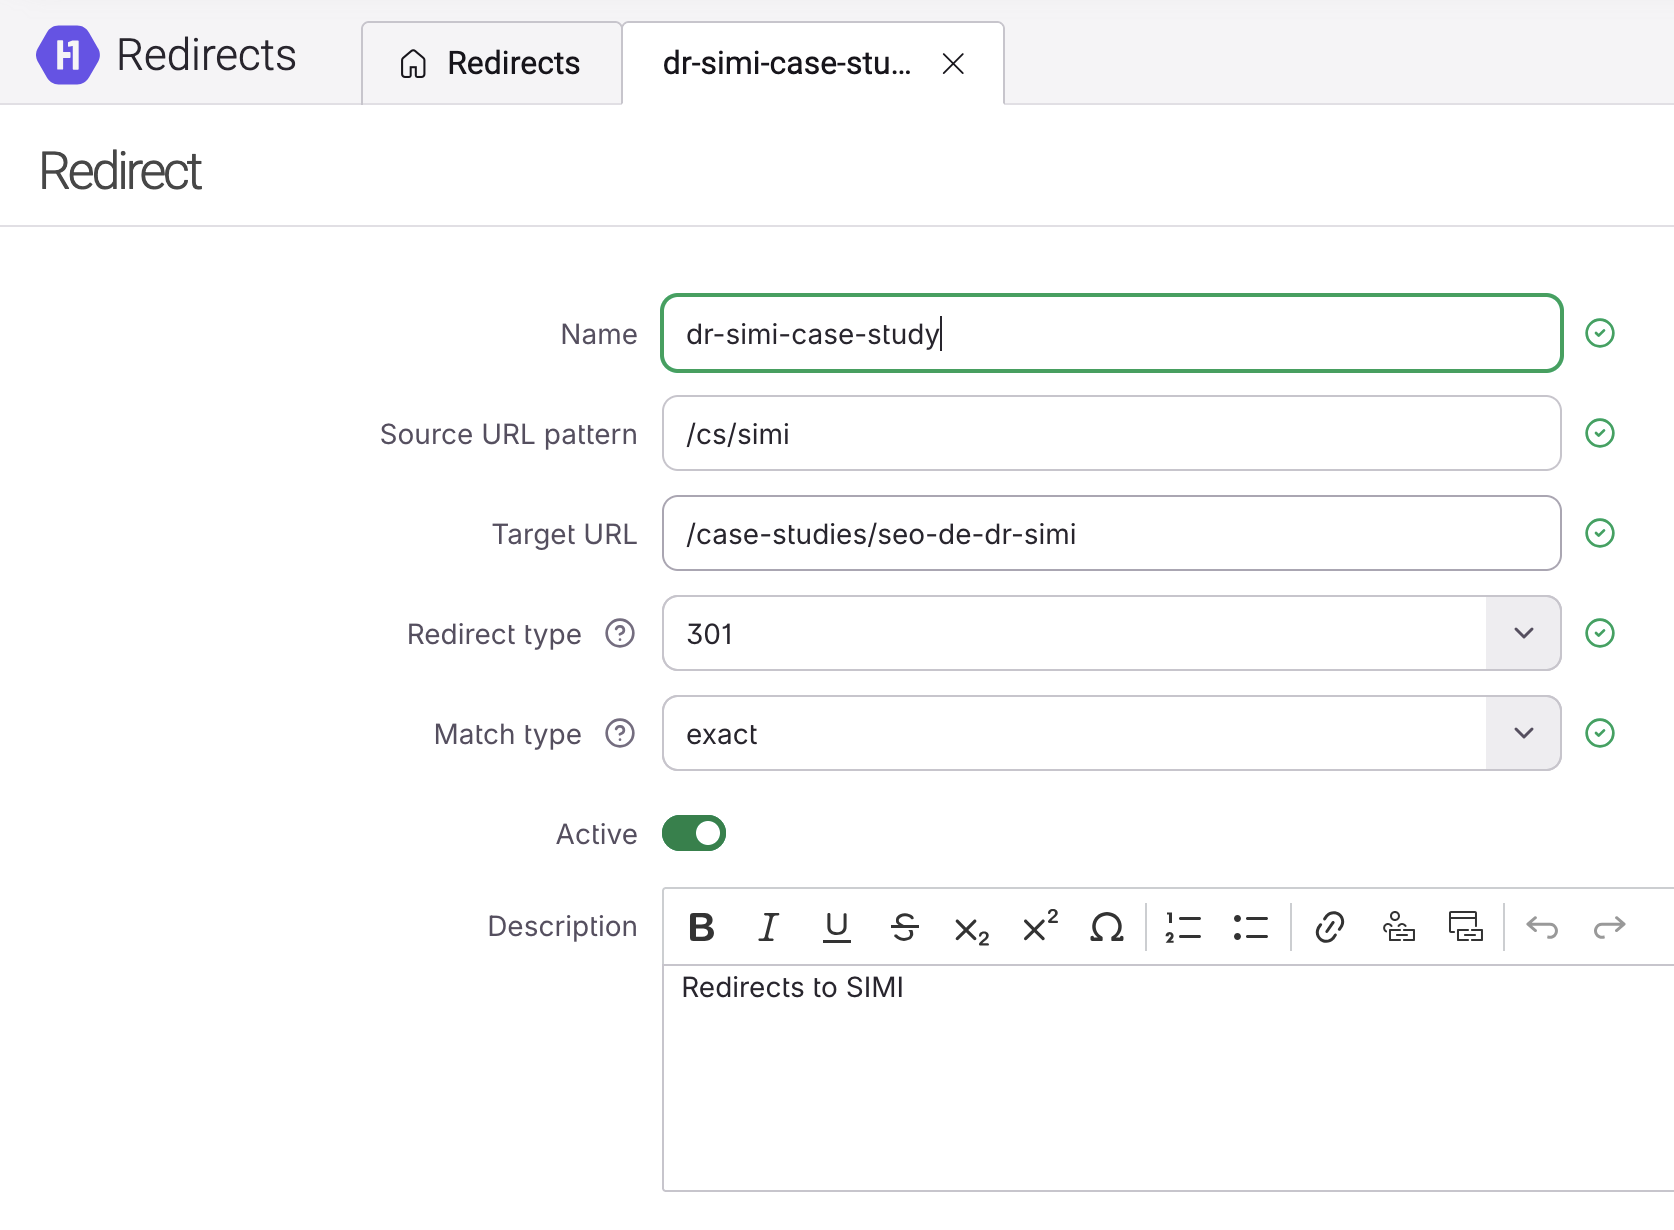
| Field | What it does |
|---|---|
| Name | The rule's own name, and the first field of the form. Required. It is how you find the rule in the list and it is the rule's identity in a CSV, so keep it stable and descriptive — dr-simi-case-study reads better in a list of two hundred than 0, and it is what makes re-importing a spreadsheet update the rule instead of duplicating it. |
| Source URL pattern | The address to catch. Required. Must start with / for an exact or prefix rule, or with ^ for a pattern rule — if it does not, saving is refused with "Must start with / (exact/prefix) or ^ (regex)". |
| Target URL | Where to send the visitor. Required. A path starting with /, or a full https://… address on another domain. |
| Redirect type | 301 permanent (default — moves the ranking to the new address) or 302 temporary (campaigns, maintenance). |
| Match type | exact (default), prefix or regex — see below. |
| Description | Internal notes: why the rule exists, who asked for it. Never shown to visitors. Optional, and it is a rich text field, so you can paste a link to the ticket. |
| Active | Turn a rule off without deleting it. A rule that is not active is never applied and is never published — switched off it behaves exactly like a deleted rule, except you keep it. |
Note — Name is the one field you cannot change later without consequences. It is the rule's identity in the CSV round trip, so renaming a rule and then re-importing a spreadsheet that still carries the old name creates a second rule instead of updating the first. See Bulk import and export.
The three match types
| Type | Catches | Example |
|---|---|---|
| exact | One specific address, nothing else. | /about-us → /company |
| prefix | A whole section, keeping the rest of the address. Write the pattern with or without a trailing /* — both work. |
/cs/* → /case-studies/ turns /cs/acme into /case-studies/acme |
| regex | Flexible patterns, with $1-style substitution. Anchor it with ^…$. |
^/blog/(\d+)/(.*)$ → /news/$2 |
Pick prefix to rename a section, exact for a single address, regex only when the address has to be transformed.
Which rule wins
When several rules match the same address the most specific one wins, and specificity is computed for you — there is no priority to set by hand:
- exact beats prefix, which beats regex.
- Between two rules of the same type, the longer pattern wins.
So a rule for /cs/acme always takes precedence over a prefix rule on /cs/*, which is how you
make one exception inside a section you have already moved wholesale.
Languages
On a multilingual site you normally leave the language out of both fields. A rule written as
/products/old catches /es/products/old and /en/products/old, and the visitor keeps the
language they were reading in. Write a language only when you mean it: in Source URL pattern to
restrict the rule to that language, or in Target URL to move the visitor to another one.
Bulk import and export
In a migration you will not type hundreds of rules one by one.
- Select the root — or a brand folder — and click Import from CSV.
- Click CSV template to download a spreadsheet with the right columns, or Full CSV export to start from the rules you already have.
- Fill it in, upload it under CSV file, and click Import.
- Export to CSV in the list view downloads the current rules for auditing, or to edit in bulk and re-import. Standing in a brand folder exports that folder only.
📸 [Screenshot: the Import Redirects from CSV dialog, showing the CSV file upload field and the CSV template / Full CSV export / Import buttons in the footer]
The columns of the file, in order:
| Column | What goes in it |
|---|---|
marca |
The brand folder the rule belongs to. Empty means the root. |
name |
The rule's identity — the same Name you see in the form. Keep it exactly as exported and the row updates that rule; change it and you create a new one. On a row written from scratch you can leave it empty: it is then derived from the source pattern. |
sourcePattern |
Same as Source URL pattern. |
targetUrl |
Same as Target URL. |
redirectType |
301 or 302. |
matchType |
exact, prefix or regex. |
description |
Same as Description. |
active |
true or false. |
A row with an error does not abort the import: the valid rules are created and you get a message telling you how many were created, how many updated and how many failed.
Note — the round trip is safe: re-importing an export updates the rules instead of duplicating them, as long as you keep the
namecolumn untouched. That column is the identity of the row, and themarcacolumn decides which brand folder a rule belongs to — the folder written in the file wins over the folder you happen to have open.
Where rules apply
A rule works on the public site and inside the platform, and takes effect within a minute of saving — no deployment, no restart.
Warning — brand folders organise the list, they do not scope it. A rule filed under
/brand-ais applied to any address that matches it, whichever brand the visitor is on. Write the brand into the Source URL pattern if you need the rule to apply to one brand only.
One set of artifacts per brand
Everything in this page works per brand, and the rule is the same everywhere: the location decides the scope.
| Artifact | Whole site | Brand /brand-a only |
|---|---|---|
| Sitemap | sitemap page at the root → /sitemap.xml |
sitemap page under /brand-a → /brand-a/sitemap.xml |
| robots.txt | robots page at the root → /robots.txt |
robots page under /brand-a → /brand-a/robots.txt |
| llms.txt | llms page at the root → /llms.txt |
llms page under /brand-a → /brand-a/llms.txt |
| Redirects | Rules at the root of the app | Rules in the brand-a folder — for organisation only, see the warning above |
Adding a brand is therefore a matter of asking a developer for those three pages under its section; the metadata tab and the redirects app need nothing.
Asking the assistant to do it
If the AI Chat app is installed on your instance, the assistant can operate all of the above for you, with the same rules and the same validations — it goes through the module, not around it. Useful when the work is repetitive.
| Ask it to | Example |
|---|---|
| Read or write the SEO of a page or an item | "Fill in the title, description and summary of /services/consulting, in Spanish and English" |
| Preview what the page will publish, before saving | "Show me the metadata /about-us would publish" |
| Clear a field you filled in by mistake | "Clear the raw JSON-LD of /products/shoes" |
Check the generated sitemap, robots or llms.txt |
"How many addresses does the sitemap of /brand-a have?" |
Create the sitemap, robots or llms page of a brand |
"Create the robots page for brand-a" |
| Create a redirect rule, and test it before trusting it | "Redirect /cs/* to /case-studies/ with a 301, then tell me where /cs/acme ends up" |
Warning — the assistant writes real content, immediately. Ask it to show you what it is about to write when the change is wide (a whole section, every item of a collection), and check the result in the form afterwards. It cannot do anything you could not do by hand, but it can do it to many pages at once.
📸 [Screenshot: the AI Chat app with a short exchange — the author asking for the SEO of a page to be filled in, and the assistant's reply confirming the fields it wrote]